
Connect customer, product
and transaction data
to Pika's decision chain.
Pika Integrations brings customer, product and transaction data into the platform through an asynchronous REST Ingestion API and Excel/CSV import flows, creating the data foundation used by Customer Intelligence, Product Intelligence and downstream decision layers.
The objective is not to imply that every source system has a ready-made native connector. It is to provide controlled data intake through Pika's documented data contracts and ingestion paths.
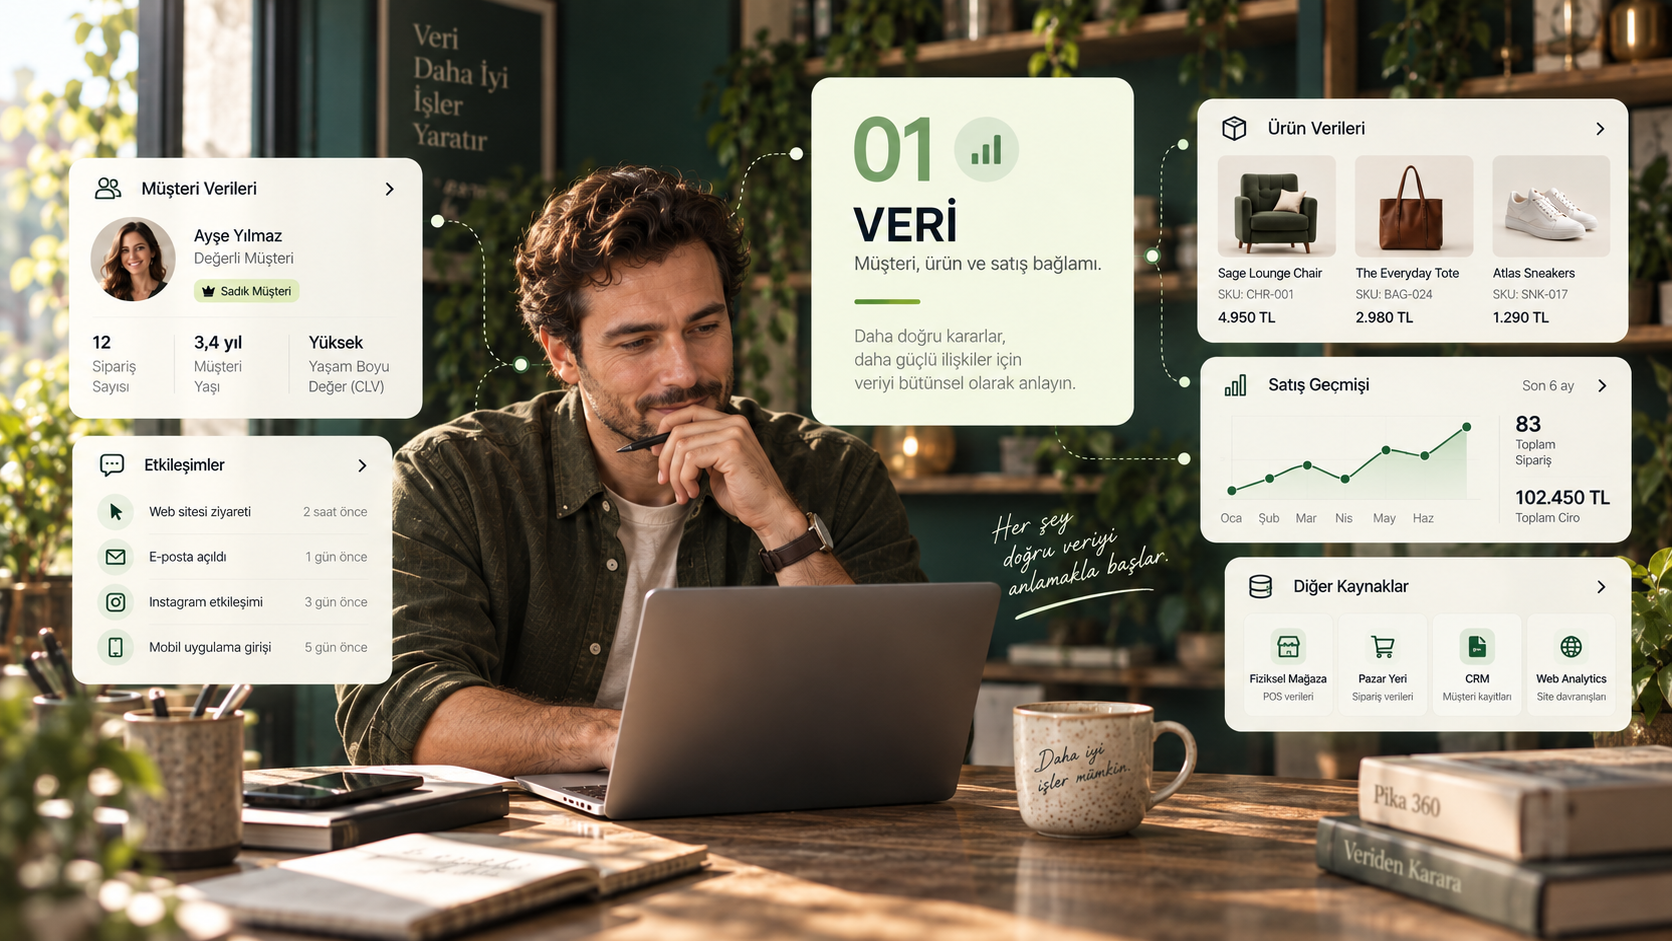
What are Pika Integrations?
Integrations is Pika's data and ingestion layer for bringing customer, product and transaction data into the platform.
Confirmed ingestion paths include Excel/CSV batch-import flows and the asynchronous REST Ingestion API under /api/v1/ingest/.
Integrations answers one central question:
“How does data enter Pika, and which decision context does it feed?”
The integration layer does not analyze the customer, create the commercial opportunity or send the campaign.
It brings data into the platform for downstream intelligence and action products.
Pika's starting point is not sending messages. It is understanding.
Decision layers such as Customer Intelligence, Product Intelligence and Daily Opportunities require usable customer, product and transaction context.
Integration is therefore more than a technical connection problem. It defines how the data required for Pika to understand customers and products enters the platform.
After data enters the platform, relevant validation, resolution and analytical processes can feed downstream decision layers.
DATA
UNDERSTANDING
OPPORTUNITY / DECISION
CONTROLLED ACTION
Integration is the entry point to Pika's decision chain.
Build Pika's data foundation with customer, product and transaction context.
Customer
Customer records, with relevant identity and communication fields, provide foundational input for customer context in the platform.
Product
Product or catalog records provide the product-side foundation used by Product Intelligence and transaction context.
Transaction
Order, sales or transaction records provide historical context for what the customer purchased and when.
Behavior, value, purchase rhythm and commercial opportunity are not simply raw fields from those records. They are context calculated in Pika's downstream intelligence and decision layers.
Integration moves the data. Intelligence creates meaning from it.
When API integration is not required, bring data in through Excel or CSV.
Pika supports Excel (.xlsx) and CSV import flows for batch ingestion of customer, product and order / transaction records.
File import is one way to bring data into Pika, particularly for initial data loads or processes that exchange data through files.
Having a file does not by itself mean the data is analytically ready. Fields may need to follow the expected data contract and pass relevant validation or mapping processes.
Excel / CSV import:
moves data into Pika.
It does not guarantee:
“Every file structure is understood automatically without mapping.”
File import is a simple but controlled integration path.
Send data from your applications to Pika through documented data contracts.
Pika's documented ingestion API root is:
/api/v1/ingest/
The API provides an asynchronous REST-ingestion approach for customer, transaction and product data domains.
Customers
Send customer records into the ingestion flow.
Transactions
Send order or transaction records into the ingestion flow.
Products
Send product or catalog records into the ingestion flow.
API access uses the documented API-key based authentication approach.
X-API-Key
The existence of an API endpoint does not mean a ready-made native connector exists for every source system. The source system must integrate with Pika's relevant data contract.
The REST API is the programmatic data-ingestion path between source systems and Pika.
Do not interpret an API request as a guarantee that everything updates at the same moment.
Pika's REST Ingestion API is designed around asynchronous processing. An accepted API request and the later availability of processed analytical context are therefore not the same concept.
The C13 public page makes no promise about a specific processing delay, real-time latency or millisecond updates.
Within the supported ingestion flow, an idempotency key can help control repeated processing when the same request is retried.
X-Idempotency-Key
helps reduce repeated processing of the same ingestion request.
is a separate process for determining whether customer or product records represent the same underlying entity.
Idempotency does not replace master-data resolution.
Moving data and creating meaning from data are different jobs.
The integration layer brings customer, product and transaction records into Pika.
Those records can later participate in relevant data-contract validation, customer identity resolution or product-matching processes.
Customer Intelligence and Product Intelligence are separate product layers that create analytical meaning from processed context.
brings data in.
prepares usable record context.
calculates commercial meaning.
“API request accepted” and “customer intelligence ready” are not the same product state.
Do not confuse a source-system category with a native-connector claim.
The origin of customer, product and transaction data can vary according to the organization's existing technology environment.
CRM
Can be one source of customer records.
E-Commerce
Can be one source of customer, product and order data.
POS / Store Systems
Can be one source of store sales and transaction records.
ERP
Can be one source system containing product, order or operational records.
Data Warehouse
Can be one source of prepared datasets that will be transferred into Pika.
These are: source-system categories.
They do not mean:
“Pika has a ready-made native connector for every product.”
The actual integration method depends on the customer's technical environment, data contract and the API or file-import path being used.
Integration brings the data. Intelligence calculates the context.
Customer and transaction data provide foundational input for Customer Intelligence to calculate context such as customer behavior, value and purchase rhythm.
Explore Customer Intelligence →
Product and transaction data provide foundational input for Product Intelligence to establish product meaning and product-relationship context.
Explore Product Intelligence →
Calculated customer and product context can then feed decision views such as Pika 360 and Daily Opportunities.
Bringing data in is the beginning of Pika's meaning-making chain.
Data enters Pika. Action happens in separate decision layers.
Customer or transaction data arriving from a source does not mean a campaign is automatically launched or a message is sent.
Data is first evaluated within relevant intelligence and decision context. Products such as Audience Manager, Content Studio, Campaign Manager or Journey Manager can then manage the controlled action process.
Customer Data
Bring customer records into the platform through Pika's verified ingestion paths.
Product Data
Bring product or catalog records in as part of the data foundation used by Product Intelligence.
Transaction Data
Bring order, sales or transaction records in as input for customer behavior and purchase-history context.
Excel / CSV Import
Bring file-based customer, product and transaction records into Pika through batch-import flows.
REST Ingestion API
Programmatically ingest customer, product and transaction data through the documented asynchronous REST API.
Idempotency
Use the supported idempotency key to help control repeated processing when ingestion requests are retried.
“How does data enter Pika?”
“How is the resulting decision executed?”
Integration is the data foundation for action. It is not the action itself.
Put Integrations in the right place.
Integrations is not Customer Intelligence.
Integrations brings data into Pika. Customer Intelligence calculates customer context.
Integrations is not Product Intelligence.
Integrations can bring product and transaction records into the platform. Product Intelligence establishes product meaning and relationships.
Integrations is not a campaign-trigger engine.
Data arriving in Pika is not by itself a decision to launch a campaign. Campaign and journey actions are managed in separate product layers.
Integrations is not a universal native-connector marketplace.
CRM, e-commerce, POS, ERP and data warehouse are source-system categories. C13 does not claim a ready-made native connector for every product.
Integrations does not guarantee real-time processing.
REST ingestion uses an asynchronous-processing approach. C13 makes no commitment about a particular processing latency, instant sync or millisecond updates.
Idempotency does not solve every duplicate-data problem.
X-Idempotency-Key helps control repeated processing of the same request. Customer or product master resolution is a separate data problem and process.
File import does not automatically understand every schema.
Excel or CSV data may need to follow the expected data contract and pass mapping or validation where required.
Integrations is not positioned as an ETL or iPaaS platform.
C13's product role is to bring customer, product and transaction data required by Pika into the platform through verified ingestion paths.
The role of Integrations is not:
To claim connection to every system.
It is:
To bring the data Pika requires into the decision chain through verified API and file paths.
Frequently Asked Questions
What are Pika Integrations?
Can data be imported into Pika through Excel or CSV?
Does Pika provide a REST API for data ingestion?
/api/v1/ingest/ provides programmatic ingestion flows for customer, transaction and product data domains.
Does the REST Ingestion API operate in real time?
What is X-Idempotency-Key used for?
Does Pika have a ready-made integration for every CRM or ERP?
Does data arriving in Pika automatically launch a campaign?
What happens after data enters Pika?
Bring data into Pika. Build context in the intelligence layers. Manage action under control.
Let's evaluate how Pika's asynchronous REST Ingestion API and Excel/CSV import flows can bring your customer, product and transaction data into the beginning of the decision chain.
Pricing is tailored to your requirements and scope of use.